> ## Documentation Index
> Fetch the complete documentation index at: https://forge-64364c0e.mintlify.site/llms.txt
> Use this file to discover all available pages before exploring further.
# Convert
> Convert SafeTensors models to GGUF format with configurable output types
# Convert (05)
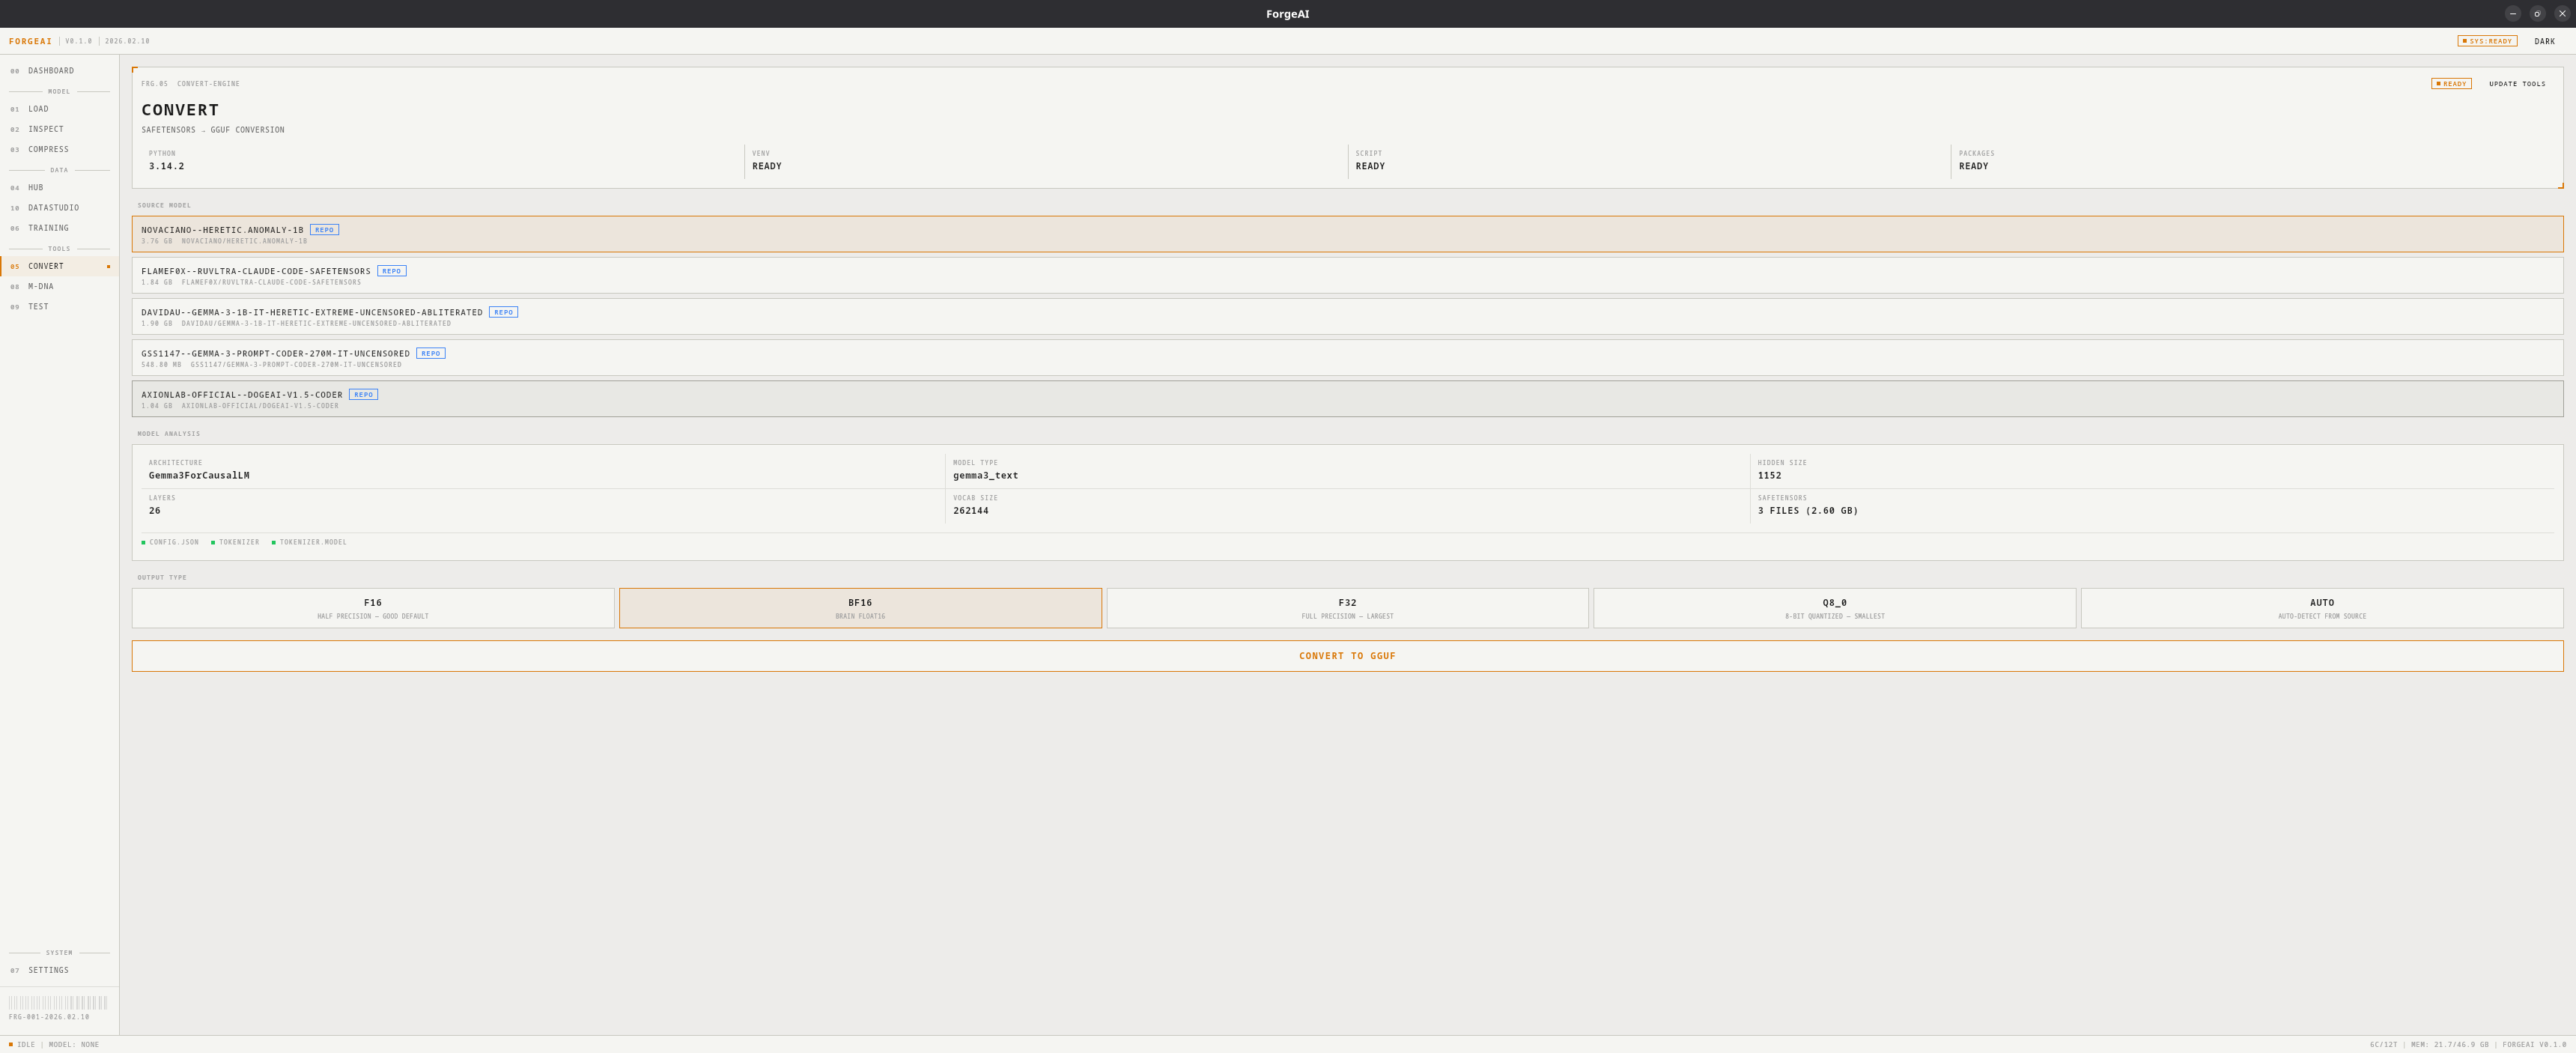
Convert SafeTensors models (HuggingFace format) to GGUF files compatible with llama.cpp, Ollama, LM Studio, and other GGUF-based runtimes.
 Requires **Python 3.10+** and a one-time dependency setup (\~500 MB). The convert environment is separate from the training environment and can be managed in [Settings](/modules/settings).
## First-Time Setup
ForgeAI checks for Python 3 on launch
Click **INSTALL DEPENDENCIES** — creates a virtual environment with `transformers`, `torch`, `safetensors`, `sentencepiece`, `protobuf`
ForgeAI detects your GPU and installs the right PyTorch variant (CUDA for NVIDIA, CPU otherwise)
The hero panel shows status indicators: PYTHON, VENV, SCRIPT, PACKAGES.
## Output Types
| Type | Description | Use Case |
| --------- | ---------------------- | ----------------------------------- |
| **F16** | 16-bit float (default) | Best balance of size and precision |
| **BF16** | Brain float 16 | Better precision for large models |
| **F32** | Full 32-bit float | Maximum precision, largest file |
| **Q8\_0** | 8-bit quantized | Smaller output, slight quality loss |
| **AUTO** | Detect from source | Matches source precision |
## Model Analysis
After selecting a source, ForgeAI shows:
| Field | Description |
| ------------ | ------------------------------------------- |
| ARCHITECTURE | Model architecture (e.g., LlamaForCausalLM) |
| HIDDEN SIZE | Embedding dimension |
| LAYERS | Number of transformer layers |
| VOCAB SIZE | Tokenizer vocabulary size |
| SAFETENSORS | Number of weight files |
File checks verify: `config.json` (required), tokenizer files, safetensors weights.
## Workflow
Pick a SafeTensors repo from the list (downloaded via [Hub](/modules/hub)) or click **GO TO HUB**
Check architecture, file counts, and file checks
Select F16, BF16, F32, Q8\_0, or AUTO
Click **CONVERT TO GGUF**, choose output location, monitor progress
See output path and size. Click **LOAD MODEL** to use immediately in ForgeAI.
After conversion, you can quantize the GGUF output further using the [Compress](/modules/optimize) module to create smaller variants (Q4\_K\_M, Q5\_K\_M, etc.).